How LLMs Work: A Beginner's Guide to Large Language Models
In short: a large language model (LLM) is a program that writes by predicting the next small piece of text, called a token, over and over. It learned which tokens tend to follow which by being trained on a huge amount of text, and it uses a design called the transformer to look back at everything written so far before each prediction.
That is the whole trick. ChatGPT, Claude, Gemini and the other chatbots you have used are all built on this idea. The rest of this guide explains each part in plain language, with no maths needed.
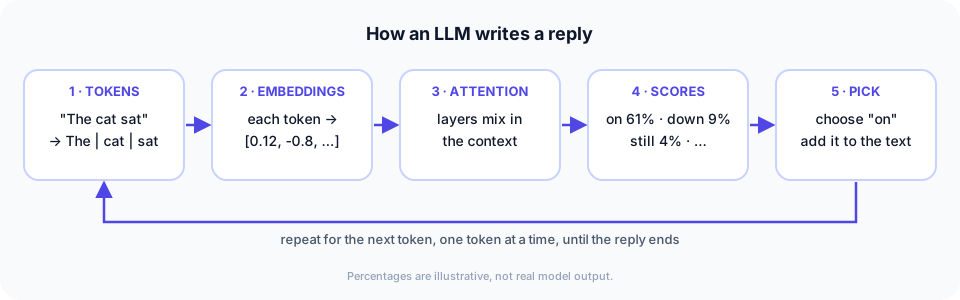
The loop in the picture: 1. your text is split into tokens; 2. each token becomes a list of numbers (an embedding); 3. transformer layers use attention to mix in the surrounding context; 4. the model gives every possible next token a score; 5. it picks one, adds it to the text, and starts again.
What is a large language model, in plain English?
A large language model is a very well-read autocomplete. Your phone's keyboard suggests the next word from a few you have typed; an LLM does the same job with far more context and far more practice, so its suggestions can add up to a whole essay, a working program or an answer to a question.
The three words in the name each mean something:
- Large - it has billions of internal settings (called parameters) and was trained on a very large amount of text.
- Language - it works with text: words, code, numbers written as text.
- Model - it is a mathematical model of how text usually continues, not a database of facts.
That last point matters later: an LLM does not look facts up unless it is connected to a tool that does. It writes what is likely to come next, which is usually right and sometimes not.
Step 1: Tokens - how an LLM reads text
An LLM does not read letters or whole words; it reads tokens, which are common chunks of text. A token is often a whole short word ("cat"), part of a longer word ("un" + "believ" + "able"), a space, or a punctuation mark.
Splitting text this way lets a model handle any word - including names and typos it has never seen - by building it from smaller known pieces. Most modern tokenizers use a method called byte-pair encoding, which starts from single characters and repeatedly merges the pairs that appear together most often (Sennrich et al., 2016).
How long is a token? For English text, OpenAI's rough estimate is that 1 token is about 4 characters, or about three-quarters of a word, and 100 tokens is about 75 words. Other languages split differently, so the same sentence can cost more tokens in, for example, Hindi or Japanese.
This is why everything about LLMs is measured in tokens:
- Prices are quoted per million tokens - see what a token is and how per-token pricing works.
- Context windows (how much text a model can consider at once) are counted in tokens.
- Output limits are counted in tokens.
Step 2: Embeddings - turning tokens into numbers
A computer cannot do maths on the word "cat", so each token is turned into a long list of numbers called an embedding. You can think of an embedding as the token's coordinates on a giant map of meaning.
On that map, tokens used in similar ways end up close together: "cat" sits near "dog" and "kitten", and far from "invoice". The model is not told where to put anything; it learns the positions during training, because placing similar words near each other makes predictions easier.
The idea is older than LLMs. A well-known 2013 study of word embeddings found that the map even captures relationships: the direction from "man" to "woman" was roughly the same as from "king" to "queen", so "king - man + woman" landed near "queen" (Mikolov et al., 2013).
Word order is added separately. An embedding says what a token is, not where it is in the sentence. "Dog bites man" and "man bites dog" use the same tokens, so the model also adds position information. Many current models use a technique called rotary position embedding (RoPE) for this (Su et al., 2021).
Step 3: Attention - how the model uses context
Attention is how the model decides which earlier tokens matter for the one it is working on. It is the core idea of the transformer, the design almost every LLM is built on, introduced in the 2017 paper "Attention Is All You Need" by researchers at Google. Our guide to the transformer paper goes through it section by section.
Take the sentence "The cat sat on the mat because it was tired." To make sense of "it", the model has to work out that "it" means the cat, not the mat. Attention does exactly that: for the token "it", it gives every earlier token a weight, and "cat" gets the most.
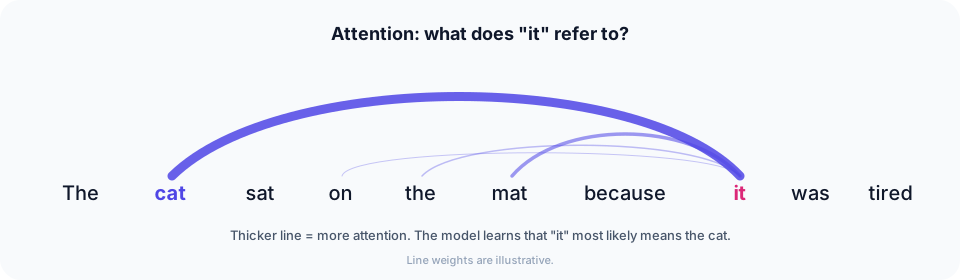
Thicker lines mean more attention. The weights are illustrative; a real model has many attention patterns running at once.
A few details that make this work at scale:
- Many heads at once. Each layer runs several attention "heads" in parallel. One might track which noun a pronoun refers to, another might track grammar, another the topic.
- Many layers stacked. The output of one layer feeds the next, so later layers work with richer, more context-aware versions of each token.
- Everything in parallel. Earlier designs read text one word at a time; a transformer processes all the tokens of the input together, which is why it could be trained on so much data.
Step 4: Parameters and layers - what "billions of parameters" means
Parameters are the numbers inside the model that training adjusts - the knobs that store everything it has learned. The embedding map, the attention weights and the other calculations in each layer are all made of parameters.
When a model is described as having, say, 175 billion parameters - the size OpenAI reported for GPT-3 in 2020 (Brown et al., 2020) - that is a count of these knobs. More parameters give a model more room to store patterns, but size alone does not decide quality; how much good data it was trained on matters too, as our guide to AI scaling laws explains.
Many current models do not use all their parameters for every token. A mixture-of-experts model has many specialised sub-networks and only switches on a few per token. NVIDIA's Nemotron 3.5 Super VL, for example, has 120 billion parameters in total but 12 billion active per token. Several labs, including Anthropic, OpenAI and Google, do not publish parameter counts for their models at all.
Step 5: Picking the next token - and why answers vary
After all the layers, the model gives every token in its vocabulary a probability of coming next, then one is picked. For "The capital of France is", "Paris" gets a very high probability and almost everything else gets very little.
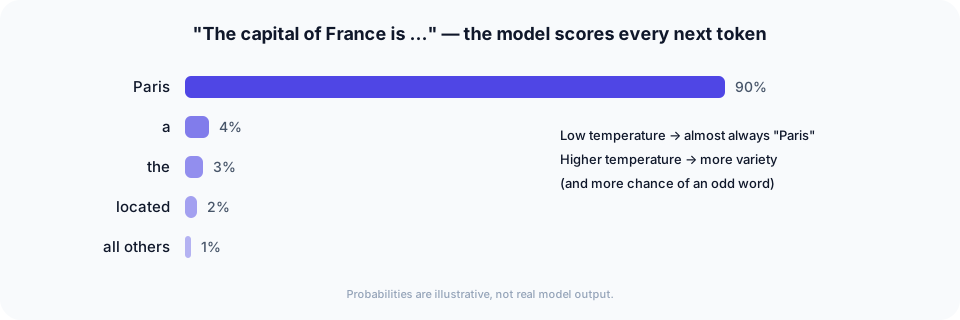
Illustrative probabilities. At low temperature the top token is chosen almost every time; at higher temperature less likely tokens are chosen more often.
How the pick is made is controlled by a setting called temperature. A low temperature makes the model choose the most likely token nearly every time, so answers are focused and repeatable. A higher temperature lets less likely tokens through more often, so answers are more varied - and occasionally stranger. OpenAI's API documentation describes it the same way: higher values make output more random, lower values more focused and deterministic (OpenAI API reference).
This is why asking a chatbot the same question twice can give two different answers. Nothing is broken; the model sampled a different path.
The picked token is added to the text, and the whole process runs again for the next token. A 500-word answer is roughly 670 tokens, so the model runs this loop about 670 times.
Step 6: Training - how an LLM learns
Training happens in stages: first the model learns language from a vast amount of text, then it is taught to be a helpful assistant.
1. Pre-training. The model reads enormous amounts of text - web pages, books, code and more - and practises one task: predicting the next token. Each time it guesses wrong, its parameters are nudged so the right token becomes a little more likely. Repeated billions of times, this teaches grammar, facts, writing styles and reasoning patterns as a side effect. No one labels the data; the text itself provides the answers. The result is a base model, which continues any text you give it but does not yet behave like an assistant: ask it a question and it may simply write more questions.
2. Fine-tuning on instructions. The base model is then trained on example conversations written or checked by people, showing the behaviour developers want: answering the question, following instructions, saying when it cannot help.
3. Learning from feedback. People (and, increasingly, other models) compare pairs of answers and mark which is better, and the model is adjusted toward the preferred kind. This is called reinforcement learning from human feedback, or RLHF. OpenAI's 2022 InstructGPT paper reported that people preferred the answers of a 1.3-billion-parameter model trained this way over those of the 175-billion-parameter GPT-3 (Ouyang et al., 2022) - feedback training changed behaviour more than size did.
These later stages are what turn a raw text predictor into ChatGPT, Claude or Gemini, and they shape much of each assistant's tone and "personality".
How a chatbot like ChatGPT puts it all together
A chatbot is an LLM inside an app that formats your conversation, sends it to the model, and shows the reply as it is generated. When you type a message:
- The app combines hidden instructions from the developer (a "system prompt"), the earlier messages in the chat, and your new message into one block of text.
- That text is split into tokens and sent to the model.
- The model generates the reply token by token, which is why you see it appear word by word.
- The app may also let the model use tools - search the web, run code, read a file - and feed the results back in as more text.
Because the whole conversation is sent each time, the model only "remembers" what fits in its context window.
Context windows: how much an LLM can read at once
The context window is the maximum number of tokens a model can take into account at one time - your prompt, any documents, the conversation so far and its own reply all count. Anything beyond it is cut off or summarised.
Context windows have grown a lot. Here is the newest model from each of five major labs, with figures that update automatically from our model database:
| Model | Context window | Input price (per 1M tokens) | Output price (per 1M tokens) |
|---|---|---|---|
| Claude Opus 5.5 (Anthropic) | 1M | $4 | $20 |
| GPT-6.1 Sol (OpenAI) | 1.05M | $2 | $10 |
| Gemini 4 Argon (Google) | 1.05M | $2 | $10 |
| Grok 4.7 (xAI) | 500K | $2 | $6 |
| DeepSeek V4.1 Flash (DeepSeek) | 1M | $0.30 | $1.20 |
At OpenAI's estimate of about 75 words per 100 tokens, a 1-million-token window holds roughly 750,000 words of English - several long novels. A large window does not guarantee the model uses every part of it equally well, which is why long-document tests are run separately. For how these figures compare across all models, see the benchmarks and rankings table.
Why LLMs make mistakes ("hallucinations")
An LLM can state false things fluently because it is trained to produce likely text, and likely text is not always true text. When it does not have the right information, the most probable continuation can still be a confident-sounding answer - an invented citation, a wrong date, a function that does not exist. This is called hallucination, and it is a well-documented, open research problem (Ji et al., survey, 2023).
Common causes:
- Gaps in training data - the topic was rare or absent.
- Out-of-date knowledge - training data stops at a cutoff date, so later events are unknown unless a tool supplies them.
- No built-in fact check - nothing inside a plain LLM compares its answer against a source.
What reduces it: giving the model the relevant documents, letting it search, asking it to cite sources, and checking anything important yourself.
Retrieval: letting an LLM look things up
Retrieval-augmented generation (RAG) means finding relevant documents first and putting them into the prompt, so the model answers from that text instead of from memory alone. The approach was described in a 2020 paper from Facebook AI Research (Lewis et al., 2020).
A typical setup: your documents are split into chunks, each chunk is turned into an embedding, and when you ask a question the chunks closest to it in meaning are fetched and handed to the model. Web search in a chatbot works on the same principle. Connecting models to data and tools in a standard way is also what the Model Context Protocol (MCP) is for.
What "reasoning" or "thinking" modes add
Reasoning modes let a model write out working steps before its final answer, which helps on multi-step problems like maths and debugging. It is still next-token prediction; the model simply spends more tokens - and more time and cost - working through the problem first.
The effect was first shown with prompting: asking a model to think step by step improved results on reasoning tests (Wei et al., 2022); see our chain-of-thought guide. Many current models build this in as a setting, often with effort levels from low to maximum. On the LMArena leaderboard, the same model can appear at several effort levels with different scores.
Words to know
- Token - a chunk of text a model reads or writes; about three-quarters of an English word on average.
- Embedding - a list of numbers representing a token's meaning.
- Transformer - the neural-network design behind LLMs, built around attention.
- Attention - the mechanism that weighs which earlier tokens matter for the current one.
- Parameters - the learned numbers inside a model.
- Context window - how many tokens a model can consider at once.
- Temperature - the setting that controls how random the next-token choice is.
- Pre-training / fine-tuning / RLHF - the three main training stages.
- Hallucination - a fluent but false output.
- RAG - retrieving documents and adding them to the prompt.
Where to go next
Frequently asked questions
How do LLMs like ChatGPT work?+
ChatGPT is an app built on OpenAI's large language models. When you send a message, the app turns the whole conversation into tokens, and the model predicts the reply one token at a time, using attention to take the earlier text into account. The model learned to do this by training on a very large amount of text and was then fine-tuned with human feedback to act as a helpful assistant.
Is ChatGPT an LLM or generative AI?+
Both. Generative AI is the broad category of AI that creates new content such as text, images or audio. A large language model is a type of generative AI that works with text. ChatGPT is a chatbot application that runs on OpenAI's GPT family of large language models.
What is the difference between GPT and an LLM?+
LLM is the general term for any large language model. GPT, short for Generative Pre-trained Transformer, is the name of OpenAI's own family of LLMs, introduced in 2018. So every GPT model is an LLM, but Claude, Gemini, Llama and DeepSeek are LLMs too.
What is the difference between an LLM and AI?+
Artificial intelligence is the whole field of making computers do tasks that normally need human intelligence. Machine learning is the part of AI where systems learn from data, deep learning uses large neural networks, and large language models are deep-learning models trained on text. An LLM is one kind of AI, not all of it.
Do LLMs understand what they are saying?+
LLMs are trained only to predict likely text, and whether that amounts to understanding is debated among researchers. In practice they can follow complex instructions and explain their reasoning, but they can also state false things confidently, so their output should be checked for anything important.
How are LLMs trained?+
In stages. Pre-training teaches the model to predict the next token across a vast amount of text. Fine-tuning on example conversations teaches it to follow instructions. Reinforcement learning from human feedback, where people rate pairs of answers, shapes it into a helpful assistant.
Why does an LLM give different answers to the same question?+
The model chooses each next token by sampling from a set of probabilities, controlled by a setting called temperature. At higher temperatures less likely tokens are chosen more often, so the same question can produce different wording or even different answers.
How many words can an LLM read at once?+
That depends on its context window, measured in tokens. By OpenAI's estimate of about 75 English words per 100 tokens, a 1-million-token context window holds roughly 750,000 words, and many current models offer windows of that size.
Related Guides
Enjoyed this? Get more in your inbox.
Up to ten of the week's AI news stories, by email once a week.